Run models from Python
Use mozo in-process when your code is Python: a script, a notebook, a pipeline or an application. There is no server to start, and nothing is sent anywhere. One call loads a model, and the model stays loaded for the life of the process.
Load a model
import mozo

model = mozo.get_model("rfdetr/medium")
A model is named family/variant. You can also pass the two separately,
mozo.get_model("rfdetr", "medium"). A family name alone is refused, even for a family with one
variant: get_model("sam3/sam3"), not get_model("sam3").
All models lists every name.
The first load downloads the weights and verifies them; later loads read the cache. Asking for the
same model again returns the same object, already loaded, so you can call get_model wherever you
need a model instead of passing it around.
get_model takes three keyword arguments:
| Parameter | Default | Description |
|---|---|---|
device |
None |
"cuda", "mps" or "cpu". None takes the best this machine has. |
progress |
None |
Called as progress(done_bytes, total_bytes) while weights download. |
cancelled |
None |
Checked once per downloaded chunk; return True to stop the download. |
def show(done, total):
    print(f"\r{done / total:.0%}", end="")

model = mozo.get_model("sam2/large", progress=show)
Run it
found = model.predict("example.jpg")predict takes a file path, encoded image bytes, or an HxWx3 RGB numpy array. When you run
several models on one image, decode it once with load_image and pass the array:
from mozo.image import load_image

image = load_image("example.jpg")
boxes = mozo.get_model("rfdetr/medium").predict(image)
depth = mozo.get_model("depth_anything_v2/indoor-small").predict(image)
What predict returns depends on what the model does:
| Models | predict returns |
|---|---|
| Detection, segmentation, keypoints, detection from words, click segmentation, OCR | a PixelFlow Detections |
| CLIP, SigLIP 2 | a PixelFlow Classifications, one score per phrase |
| Depth Anything V2 | an HxW float32 depth map |
| BEN2 | an HxW uint8 alpha matte |
| Moebius | an HxWx3 uint8 image |
The embedding families have encode_image and encode_text for vectors, and Granite Embedding R2
has only encode_text. Prompts (phrases, clicks, boxes) are arguments to predict, described on
each family's page.
A loaded model can be called from several threads at once, and in parallel it runs faster than
calling it from one thread in turn. That is safe on CPU, CUDA and ONNX Runtime. On Apple silicon
(mps) and CoreML it is tested but not documented as thread-safe by PyTorch or Apple, so put a
lock around your calls there if you need a guarantee.
Work with the results
Every detection family returns the same Detections, so filtering and drawing are written once,
whatever model produced them. They come from PixelFlow, which mozo
installs:
import mozo
import pixelflow as pf
from mozo.image import encode_image, load_image

image = load_image("example.jpg")
found = mozo.get_model("rfdetr/medium").predict(image)

people = found.filter_by_class_id([1]).filter_by_confidence(0.8)
len(found), len(people)          # (13, 4)

annotated = pf.annotate.box(image.copy(), people)
annotated = pf.annotate.label(annotated, people)

with open("people.png", "wb") as file:
    file.write(encode_image(annotated))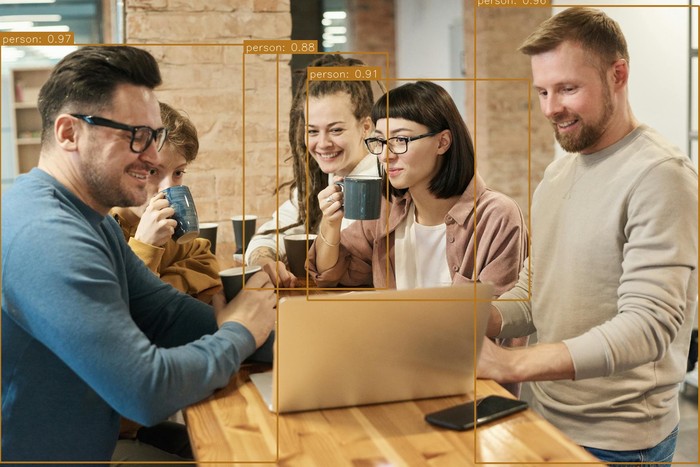
A detection has bbox, class_id, class_name and confidence, plus masks, keypoints,
text or segments when the model fills them. found.to_json() and found.to_dict() give the
same structure the HTTP server returns.
Class ids are the model's own: RF-DETR uses COCO's original ids, where
person is 1, and the YOLO families number them from 0. Filter by class_name when you mix
models.
Manage memory
Nothing is unloaded automatically. A model stays loaded until you release it, because only you know which models you will need again:
mozo.unload("rfdetr/medium")     # True if it was loaded
mozo.clear()                     # release every model get_model loaded
Both give accelerator memory back to the driver. For a separate set of models with its own
lifetime, for example a batch job that should release everything at the end, build your own
ModelManager:
from mozo import ModelManager

models = ModelManager()
model = models.get_model("rfdetr", "nano")

models.resident()
# [{'id': 'rfdetr/nano', 'family': 'rfdetr', 'variant': 'nano', 'device': 'mps',
#   'runtime': 'coreml-fp32', 'last_used': 1795219443.46, 'size': 99897095}]
resident() reports each model's device, runtime, last use and estimated size in bytes, which is
what you need to decide what to unload. A ModelManager also takes arguments that
mozo.get_model does not, such as runtime to choose an ONNX or CoreML graph yourself:
model = models.get_model("rfdetr", "small", runtime="onnx-fp32") # pip install 'mozo[onnx]'Your own checkpoints
A model you fine-tuned on an architecture mozo supports loads through the same call, with
checkpoint_path and the class names:
from mozo import ModelManager

models = ModelManager()

# YOLO reads the architecture from the checkpoint, so the variant is any name you choose.
hardhats = models.get_model("yolov8", "hardhats", checkpoint_path="runs/best.pt")

# RF-DETR's variant names the architecture the checkpoint was trained from.
vests = models.get_model("rfdetr", "small", checkpoint_path="runs/rfdetr/best.pth",
                         labels=["hardhat", "vest"])
The checkpoint is part of the model's identity, so two checkpoints under one variant name are two
models, not one. A YOLO checkpoint carries its class names. An RF-DETR checkpoint may not; without
labels, its detections have a class_id and no class_name, because mozo never guesses a name.
A checkpoint of your own always runs on torch.